Tech Support
 Documentation
 Login
 Contact Us


Go straight to an AI summary of this blog post instead 


Key Takeaways
- A zero-day exploit is working attack code for a vulnerability with no publicly available fix.
- Exploitation can begin before a patch exists, often before anyone outside the attacker knows.
- End-of-life software can leave new flaws with no upstream fix coming at all.
- What you control is how fast a fix reaches your fleet once one exists.
Your scanner shows a clean report. Your patch cycle is current. None of that helps when a flaw is already being exploited and no distribution has shipped a fixed package yet.
That is a zero-day exploit: attack code for a vulnerability with no publicly available fix. Sometimes that code stays private for months. Sometimes the exploit lands on GitHub the same day, which is what happened when Dirty Frag hit Linux distributions in May 2026. Either way, the exploit is only the opening move. A big part of what it ends up costing you is how long that exposure window stays open afterward.
Zero-Day Vulnerability vs Exploit vs Attack
A vulnerability is the flaw. An exploit is the working code. An attack is that code aimed at a real target. Mitigation is possible well before that last stage, and patching becomes possible once a fix exists. After exploitation starts, detection and containment are what buy you time.
| Term | What it is | Can you act on it? |
| Zero-day vulnerability | The flaw in the code, which may be privately known but is not yet publicly disclosed or patched | Not always. Until the flaw is identified there is nothing specific to patch, and after that mitigations may be possible while a fix is built. |
| Zero-day exploit | Working code that weaponizes that flaw reliably | Partly. Mitigations, module blocklists, and hardening can break the technique. |
| Zero-day attack | A live campaign using that exploit against real targets | Yes. Detection and containment apply immediately, patching once a fix ships. |
A flaw can sit in the kernel for years without anyone filing an incident report. The vulnerability was there the whole time, even if how much practical risk it carried depended on whether anything could reach it. What a working exploit changes is the odds of that risk being realized. Once the flaw or the exploitation is known, the response stages become things you can time, measure, and shorten.
Types of Zero-Day Exploits
Zero-days are not spread evenly across your stack, and the useful way to sort them is by where they land. In its report Look What You Made Us Patch, Google Threat Intelligence Group (GTIG) counted 90 zero-days exploited in the wild during 2025, up from 78 in 2024 and still short of the 100 it logged in 2023. Operating systems were the single most exploited product category at 44% of the total, or 39 flaws. Enterprise software and appliances, counted as a group rather than as one category, came to 43 flaws, or 48%, which GTIG reports as the highest on both counts since it began tracking.
Browser exploitation went the other way and fell to historic lows. Exploitation of enterprise infrastructure and edge devices stayed elevated instead, helped along by the fact that most edge devices lack standard EDR coverage.
Operating System and Kernel Exploits
Operating systems were the largest single category in GTIG’s 2025 data, spanning desktop, mobile, and server, and Linux kernel flaws show how wide the blast radius gets. A successful compromise at that layer can undermine the boundaries between applications, containers, and tenants, and expose credentials the host is holding.
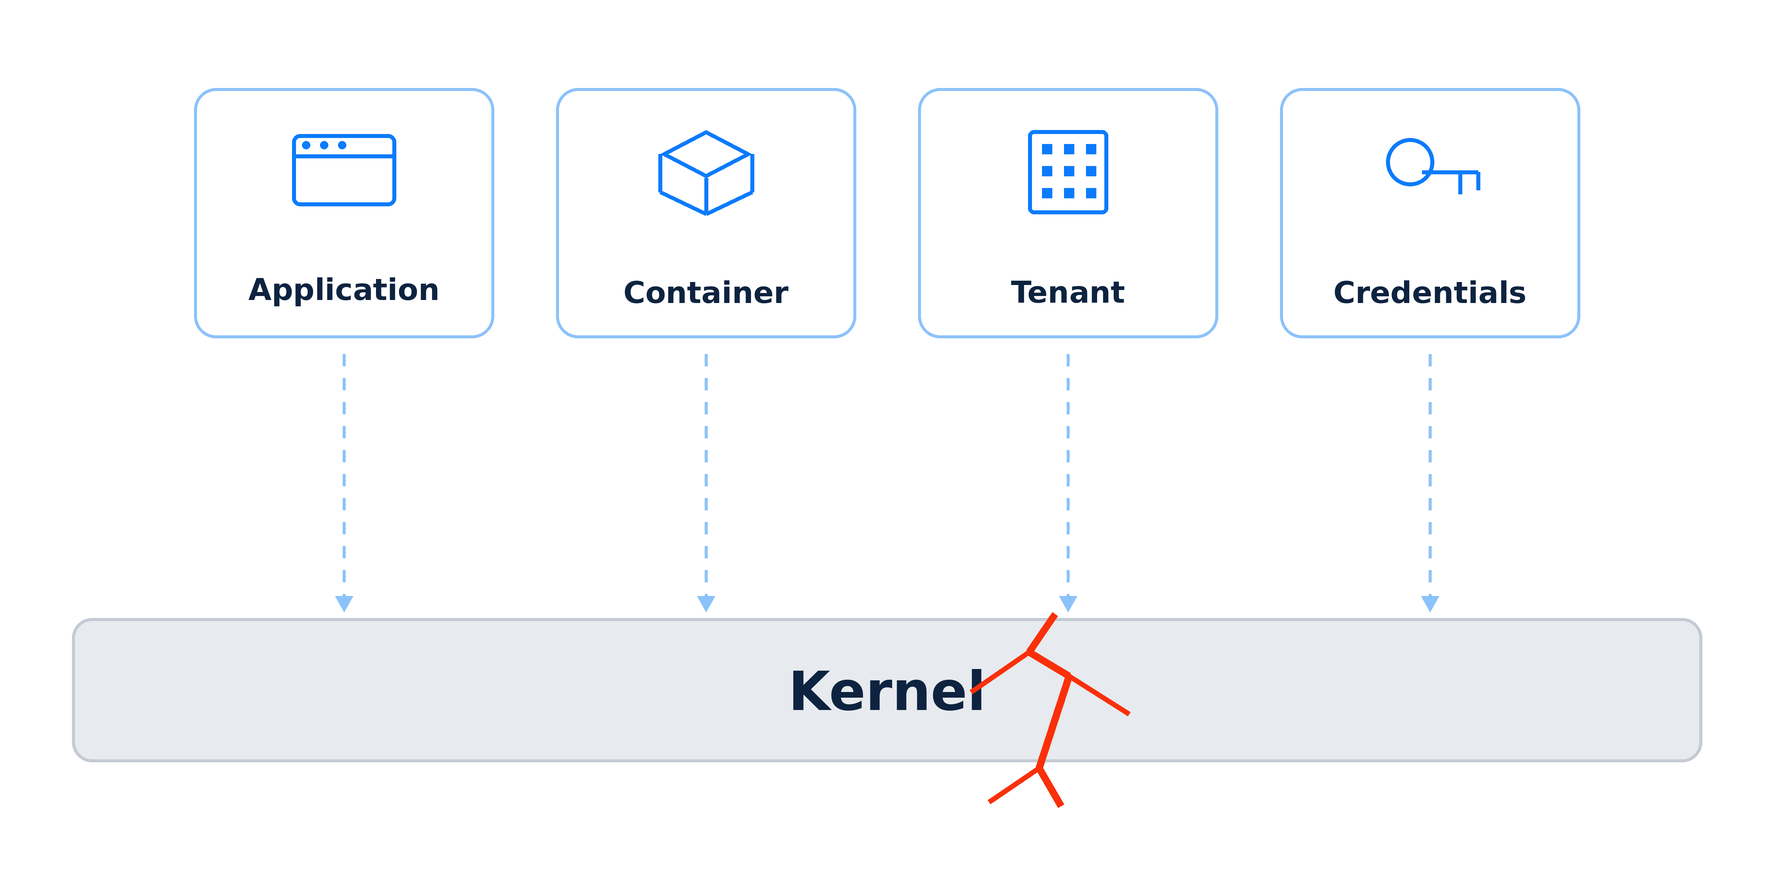
The 2026 Linux kernel privilege escalation flaws are a good demonstration. Copy Fail (CVE-2026-31431, CVSS 7.8) had been sitting in the algif_aead module of the kernel crypto API since a 2017 in-place optimization. An unprivileged local user could rewrite the in-memory page cache copy of a setuid binary such as su, four controlled bytes at a time, with no race condition and no per-distribution offsets to guess. Nothing changed on disk, so file integrity monitoring had nothing to report.
Dirty Frag turned up a week later, pairing CVE-2026-43284 in the IPsec ESP modules with CVE-2026-43500 in rxrpc. They are two independent routes to the same page-cache write rather than a chain, and the public exploit tries whichever one the host allows, so closing one path does not close the other.
TuxCare released live patches for Copy Fail after validating the full upstream fix set against the published exploit, then released Dirty Frag patches within 24 hours of the May 7 disclosure. When the exploit is public and the fix needs a reboot across a thousand hosts, the reboot can become the deployment bottleneck. Closing that particular gap is what KernelCare is for.
Did You Know: As of September 2026, CISA’s Known Exploited Vulnerabilities catalog held 31 entries for Linux kernel flaws. By the same point, one public tracker counted over 6,500 Linux kernel CVEs published during 2026. Both figures move constantly, so check them before you quote them anywhere.
Enterprise Edge and Appliance Exploits
Firewalls, VPN concentrators, file transfer appliances, and virtualization platforms are among the highest-value zero-day targets in the enterprise, and the reason is structural. They sit at the network boundary, hold privileged credentials, and mostly lack standard endpoint EDR coverage.
GTIG’s 2025 vendor breakdown puts big tech at the top with security vendors immediately behind, and singles out Cisco and Fortinet as perennial networking and security targets alongside Ivanti and VMware, where the draw is VPN and virtualization access. Another 20 vendors were hit by exactly one zero-day each, which tells you how wide attackers are willing to cast. GTIG also reported that state-sponsored espionage groups continued to prioritize edge devices and security appliances, with just over half of the zero-day exploitation it attributed to those groups aimed at that kind of infrastructure.
The pattern repeats: pre-authentication remote code execution, credential or key theft, and persistence that outlives the patch. ToolShell attackers pulled ASP.NET machine keys off SharePoint servers, which let them forge valid payloads long after the server was updated. Patching closed the vulnerability, but anyone already holding those keys kept their way back in until the keys were rotated. If your appliance inventory lives in a quarterly spreadsheet, that spreadsheet is the exposure.
Application and Supply Chain Exploits
The third category is code you didn’t write and often didn’t knowingly install. Log4Shell is the reference case, a critical flaw in Log4j, a logging library buried several levels down the dependency tree of thousands of Java applications. In a vulnerable configuration, all it took was an attacker-controlled JNDI string, for example one supplied through a logged HTTP header, reaching a vulnerable Log4j call path.
Flaws in dependencies are harder to respond to because you cannot patch what you cannot enumerate. Teams spent weeks after Log4Shell just building the inventory, and plenty are still turning up hidden Log4j exposure years later. Dependency confusion is a different animal, a supply chain attack that plants a malicious package rather than finding a bug in a legitimate one, but it feeds on exactly the same blind spot.
Screening packages before they reach a build will not reliably flag a flaw nobody has discovered yet in an otherwise legitimate dependency. What it can catch are malicious and typosquatted packages, and it hands you the dependency inventory you would otherwise be assembling in the middle of an incident. That is the gap TuxCare’s SecureChain is built to close on the open-source side.
Notable Zero-Day Exploit Examples From 2021 to 2026
The list below runs from a mail server to a logging library to a managed file transfer tool to a collaboration platform to the kernel itself. Zero-days do not stay in one layer of the stack.
| Year | Exploit / CVE | Target | Why it counted as a zero-day |
| 2021 | ProxyLogon / CVE-2021-26855 | Microsoft Exchange on-prem | Mass exploitation began before the out-of-band patch shipped |
| 2021 | Log4Shell / CVE-2021-44228 | Apache Log4j 2 | Exploitation observed days before public disclosure and fix |
| 2023 | MOVEit / CVE-2023-34362 | Progress MOVEit Transfer | Cl0p exfiltrated data before the advisory existed |
| 2025 | ToolShell / CVE-2025-53770 | SharePoint Server on-prem | CVSS 9.8 RCE exploited from July 18, ahead of the emergency patch |
| 2026 | Dirty Frag / CVE-2026-43284, CVE-2026-43500 | Linux kernel (ESP, rxrpc) | Public exploit released before any distribution shipped a fix |
Two of these have a more complicated backstory. The research behind ToolShell started as a Pwn2Own Berlin demonstration in May 2025, chaining CVE-2025-49704 and CVE-2025-49706, and Microsoft patched both that July. The vulnerability in the table is not that one.
CVE-2025-53770 is a bypass of the July fix, and it was already being exploited when Microsoft assigned it. Dirty Frag was under coordinated disclosure until somebody broke the embargo and forced early publication. Neither case needed a malicious research origin. What mattered was that exploitation was possible before defenders had a complete fix.
Why Zero-Day Exploits Are So Dangerous
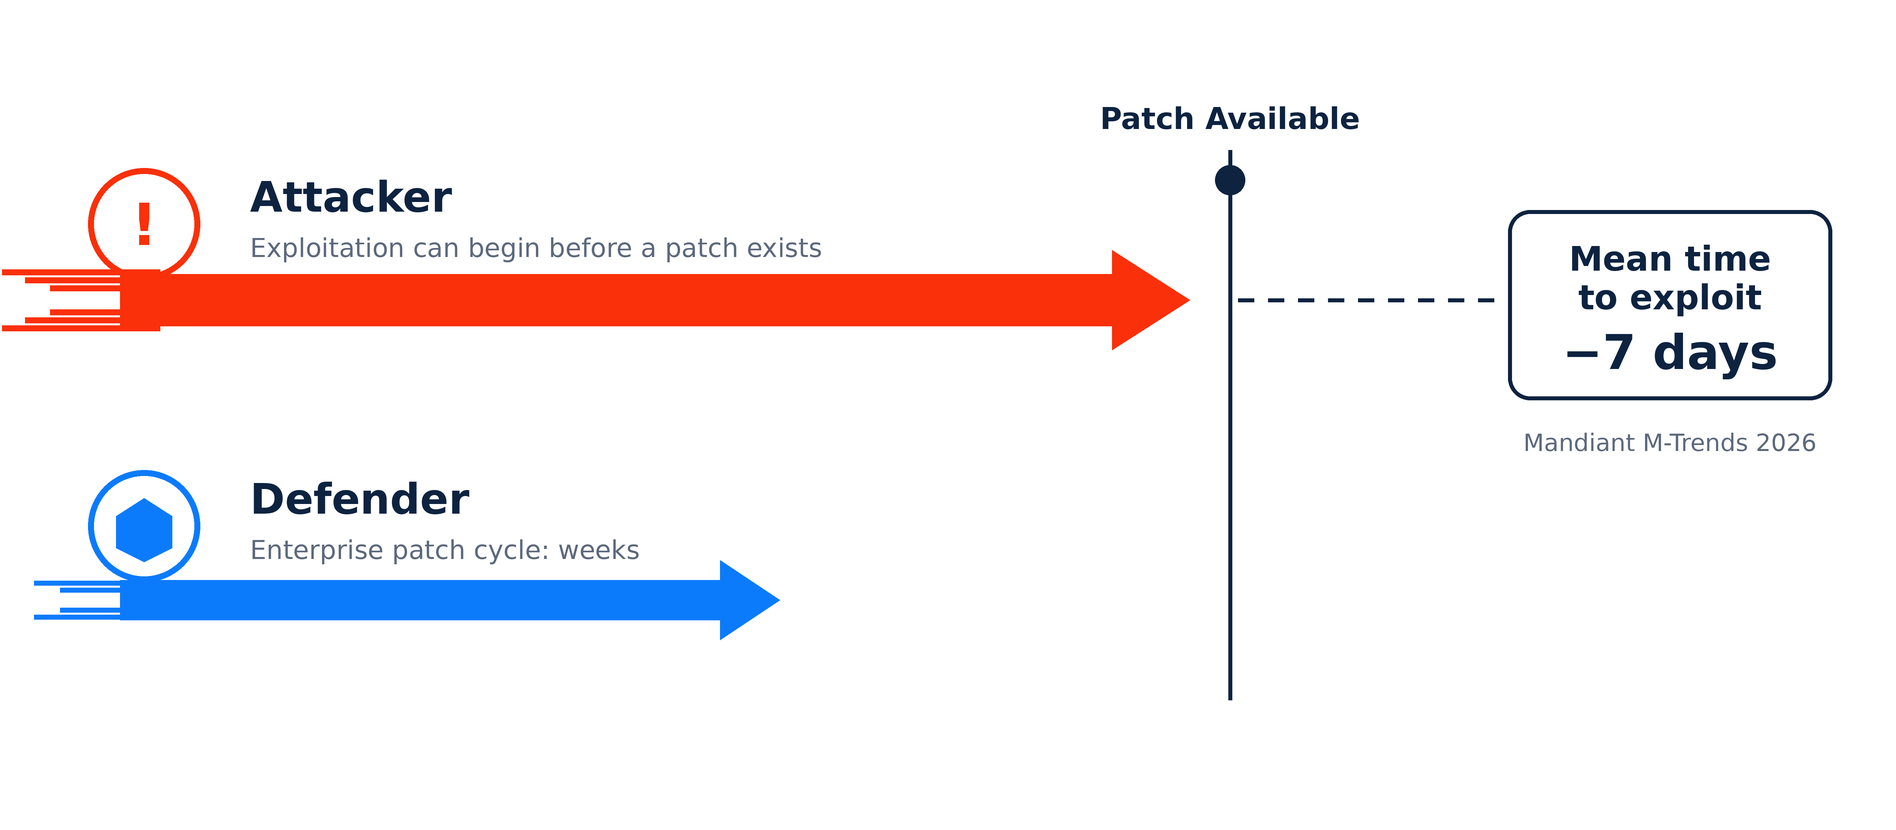
A zero-day is dangerous less because it is unknown than because of the mismatch in speed. Attackers can move in hours. Enterprise remediation, bound by testing, change control, and maintenance windows, often takes days or weeks. Mandiant’s M-Trends 2026 report puts the estimated mean time to exploit a new vulnerability at negative seven days, meaning exploitation now routinely starts before a patch exists at all. Mandiant’s own trend line had that same figure at 63 days across 2018 and 2019.
1. No Patch Exists When You Need One
Most vulnerability-management processes assume a vendor fix is available. During the pre-patch stretch of a zero-day you are on compensating controls instead: disabling a feature, restricting network exposure, changing configuration, or, on Linux, blocklisting a kernel module and tightening seccomp profiles. They cut exposure, and some of them cut legitimate functionality along with it, which is why they need testing before they go fleet-wide. For Dirty Frag, the CERT/CC workaround was to blocklist esp4, esp6, and rxrpc, unload them, and drop the page cache. That also breaks IPsec and AFS, so it was never free.
Picture the team running a 300-node Kubernetes platform getting that advisory mid-week with a public exploit already attached. Blocklisting the modules means first proving that nothing in the fleet needs IPsec, and that proof takes longer than an attacker needs on a host they can already reach.
2. Signature-Based Detection Starts at a Disadvantage
Signature-based antivirus and CVE-based scanning both lean on things somebody already identified and catalogued. A brand-new zero-day has no CVE-specific signature and no scanner check behind it yet.
Behavioral detection covers part of that gap and it is far better than it was five years ago. It is also noisy, and the 2026 kernel flaws showed where the limits are. Copy Fail only touched the in-memory page cache, so the file on disk stayed byte-identical and file integrity monitoring stayed quiet. A reboot reloaded the clean page and took that particular artifact with it.
The scanner problem stacks on top of all this. Teams drowning in false positives from misidentified backports stop reading scan output closely, which is exactly when a real finding gets waved through as noise.
3. End-of-Life Systems Can Leave Zero-Days Unpatched Indefinitely
On a supported system, a zero-day is a window that usually closes once a fix or a workable remediation arrives. On an end-of-life version, nothing more is coming from upstream for that release, so the window stays open until you find another way to close it.
That turns into security debt rather than a discrete incident. Every newly disclosed flaw that touches that version, zero-day or not, adds another unpatched item, and those accumulate.
Teams stay on EOL operating systems for real reasons: certified application stacks, hardware constraints, validation cycles measured in quarters. TuxCare’s Endless Lifecycle Support exists for that situation, providing security patches for covered EOL systems and software while migration happens on a schedule the business actually sets. It is a different problem from a zero-day, where a fix is expected but has not shipped. On an aging fleet, the two compound each other.
How to Defend Against Zero-Day Exploits
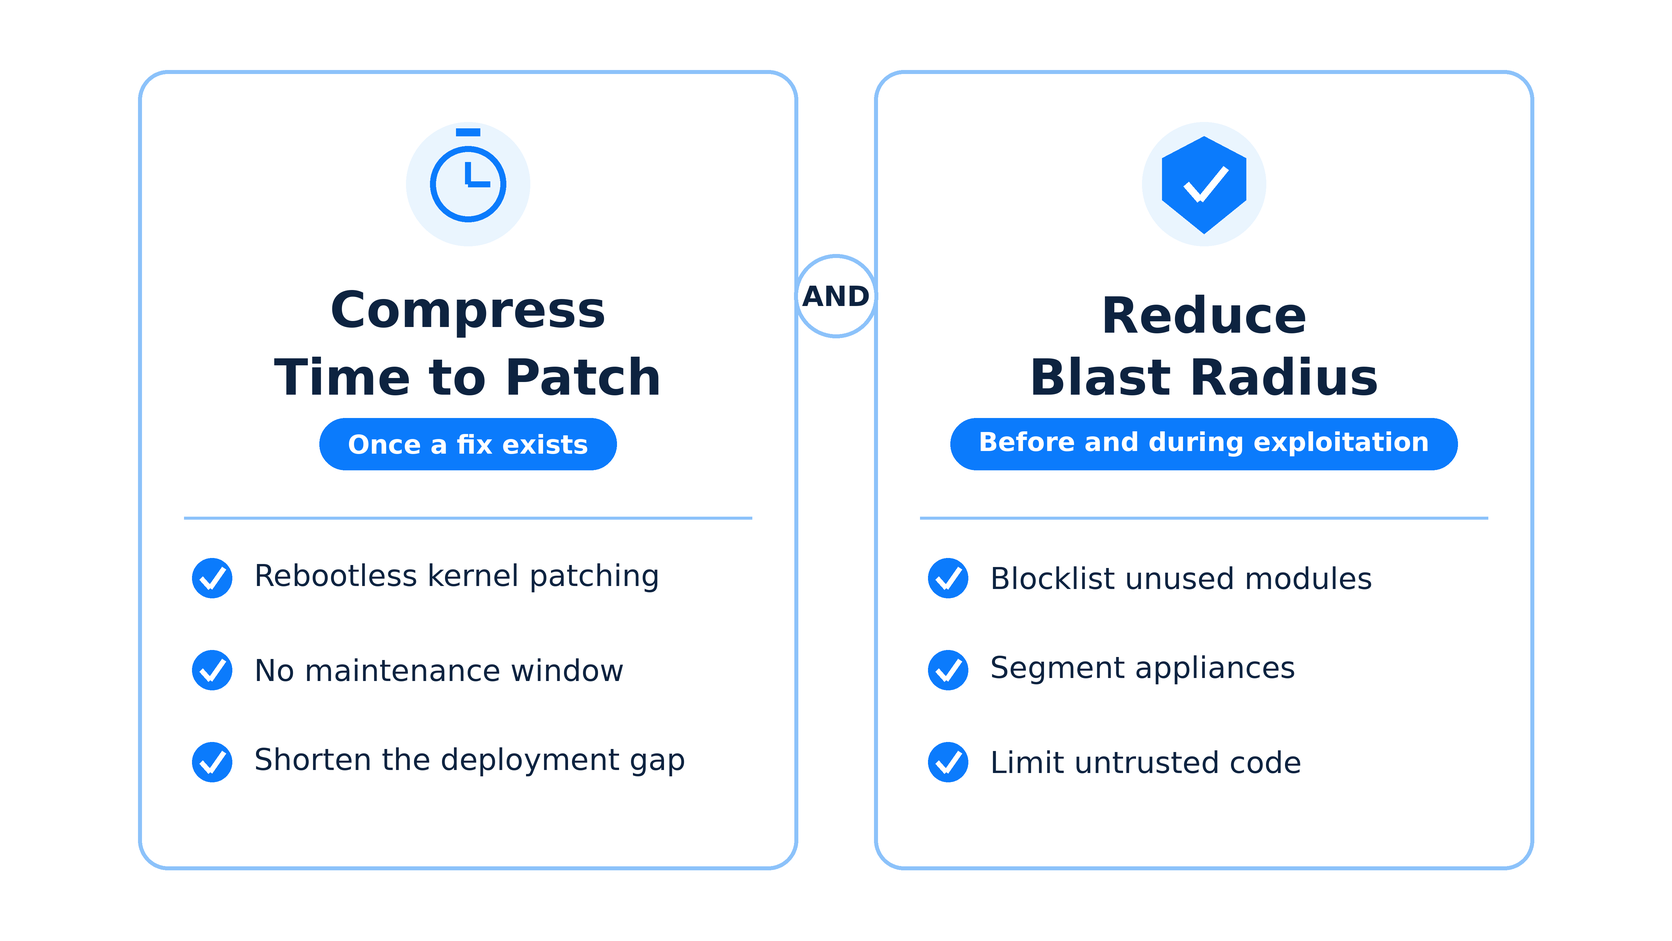
You cannot run a CVE check for something nobody has identified yet, so do not build the whole plan around that. Two goals carry most of the weight here. Shorten the time between a fix existing and that fix being live, and limit what an exploit can reach once it lands. Detection, incident response, and access control all still matter, but those two are where most teams have the most room to move.
Compress Time to Patch Once a Fix Exists
You do not control when upstream ships. What you control is the deployment window afterward, and for a lot of organizations that window, not the patch, is where the weeks go.
Rebootless patching removes the constraint at the kernel layer. If your fleet can absorb reboots inside a day, conventional patching may be perfectly adequate. If a kernel reboot means a change window three weeks out, rebootless patching can cut that deployment gap down sharply without you accepting three weeks of exposure in the meantime.
Reduce Blast Radius Before You Need To
Mitigation decisions made under pressure are bad decisions. Make them early.
That means blocklisting kernel modules nothing in your fleet uses, so the path is closed before it is ever disclosed. It means seccomp profiles on untrusted workloads, CI runners, and multi-tenant nodes. Docker’s default profile denies unshare, which blocks the user and network namespace setup the published xfrm/ESP Dirty Frag exploit needs, and testing on EKS, GKE, and Talos found RuntimeDefault enough to stop that path on an otherwise vulnerable kernel. The same testing found unset seccomp is not equivalent to RuntimeDefault on EKS or GKE, and pods running with no profile were exploited to container root, so this only helps where RuntimeDefault is actually enforced rather than assumed. Worth knowing that the same control did nothing for Copy Fail, where AF_ALG stayed reachable even under Restricted pod security. And it means keeping untrusted code away from hosts that hold production credentials, then segmenting appliances so a compromised VPN concentrator cannot reach the database tier.
Copy Fail and Dirty Frag both need local code execution. Anywhere an attacker can get that – shared CI, container build farms, multi-tenant Kubernetes, or any host reachable after an initial foothold – is where the exposure concentrates.
Know What You Actually Run and What Is Actually Patched
Response speed is capped by inventory accuracy. A team with a live view of which hosts run affected kernels can get those hosts patched sooner, which is the whole game when the exploit is already public. A team without one spends the incident building a spreadsheet.
Two things matter here. First, an accurate asset and version inventory, containers and appliances included. Second, patch verification that reflects the running system rather than package metadata, which is where scanners that infer status from version strings tend to get backported and rebootless fixes wrong.
Run the exposure drill before you need it. Normal Tuesday, made-up CVE, and see how long it takes to answer which hosts are affected and whether they are fixed. Inventory gaps are often the first thing to fall out.
Best Tools to Protect Against Zero-Day Exploits
None of these can promise to identify an unknown flaw before exploitation starts. What they do is shorten the window afterward and let you prove what state you are actually in.
1. TuxCare
TuxCare covers three different pieces of the zero-day problem, and that is deliberate rather than product sprawl, because compromise does not respect the boundary between the kernel, userspace, and the software upstream already abandoned.
KernelCare patches the running Linux kernel with no reboot and no maintenance window, across a broad range of major enterprise distributions, which matters in mixed fleets where per-OS tooling means separate contracts and separate gaps. LibCare extends the same approach to userspace libraries like glibc and OpenSSL. Endless Lifecycle Support delivers security patches for covered EOL operating systems, runtimes, libraries, and frameworks through standard package management, long after upstream stops.
2. CISA Known Exploited Vulnerabilities Catalog
Free, authoritative, and the quickest way to tell “theoretically exploitable” from “being used against people right now.” The KEV catalog lists CVEs with confirmed in-the-wild exploitation, and Federal Civilian Executive Branch agencies get binding remediation deadlines for each entry.
Use it as a triage filter. A CVE landing in KEV moves to the front of the queue regardless of its CVSS score. The catch is timing, because KEV is a lagging indicator and a zero-day is already being exploited well before it shows up there. Copy Fail was added on May 1, two days after disclosure, and the public exploit had been out for those same two days. It remains one of the strongest public signals for prioritizing confirmed exploitation.
3. Behavioral EDR and Runtime Detection
Endpoint and runtime tools that watch behavior rather than signatures can catch exploitation with no vulnerability-specific detection in place, which is the entire point of them. Runtime tools like Falco, or your own eBPF probes, can flag the syscall patterns exploits lean on, like the splice-based page-borrowing sequences the published Dirty Frag code used to reach its page-cache write primitive.
Two caveats. Detection is not prevention, so an alert still needs somebody awake to act on it. And plenty of appliances and network devices simply cannot run an agent, which is part of why GTIG counted 14 edge-device zero-days in 2025 and noted that the number likely understates the true scale.
Protect Your Systems Against Zero-Day Exploits with TuxCare
Zero-days are not going anywhere. The possibility that exploitation starts before a patch is available is a permanent feature of running software, and it will come around again without warning.
What you can control is how long the window stays open. Rebootless kernel patching takes the maintenance window out of the equation. Extended support restores a patch path for covered EOL systems. Accurate patch verification tells you which hosts are genuinely fixed instead of which ones merely look fixed.
If you run Linux at scale and kernel patching still waits on a reboot schedule, close that gap first. KernelCare is built for exactly that.
FAQs
The vulnerability is the underlying flaw. The exploit is the code or technique that uses that flaw to produce an effect nobody intended. A flaw is still a flaw whether or not anyone has written an exploit for it. The exploit is what lets an attacker actually use it against a running system.
There is no single timeline. Some zero-days get exploited quietly for months and the code never goes public at all. Others pick up proof-of-concept code within hours or days of disclosure. Dirty Frag was the fast kind, with a working exploit published on May 7, 2026, before distributions had shipped patched kernels.
Sometimes, though not by recognizing the vulnerability itself. Signature-based antivirus matches files and payloads against known malicious indicators, so it can catch a familiar payload delivered through a brand-new flaw while knowing nothing about the flaw. Behavioral and runtime tools do better at spotting novel exploit activity, and most of them alert rather than block unless you configure them to.
A zero-day attack uses a zero-day exploit against a real target, by definition before a fix is publicly available, and often before the vulnerability is widely known.
Yes. GTIG found that operating systems accounted for 44% of the zero-days it tracked in 2025, the largest single product category, and as of August 2026 CISA’s KEV catalog held 31 Linux kernel entries.
They can stay unpatched indefinitely as far as the original vendor is concerned, because upstream security fixes generally stop once a version reaches EOL. Third-party extended support is one way to keep receiving security patches after official support ends.